HiDream Unveils HiDream-O1-Video-1.0, a Native Omnimodal Video Model Built for Physical Consistency
 Media OutReach Newswire
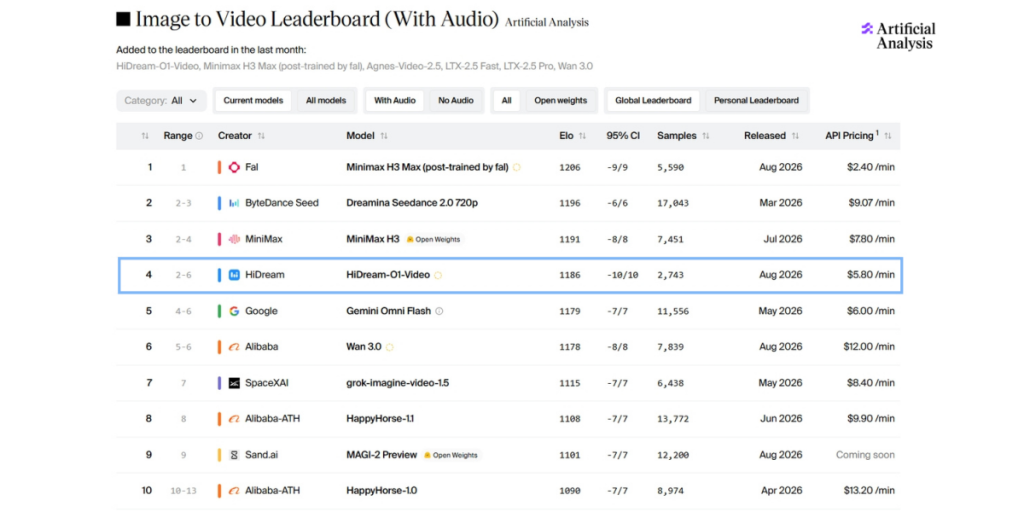
The model supports multimodal inputs including text, images and video, and generates high-fidelity 1080p videos of 5 to 20 seconds with natively synchronized audio
BEIJING, CHINA – Media OutReach Newswire – 17 September 2026 – HiDream.ai, an AI company specializing in foundation models and generative AI, announced the launch of HiDream-O1-Video-1.0, or HiDream V1, its native omnimodal video generation model.

Designed around a deeper understanding of creative intent and real-world physics, HiDream V1 supports multimodal inputs including text, images and video. It can generate high-fidelity 1080p videos ranging from 5 to 20 seconds, with enhanced narrative planning, character consistency, physical plausibility and audiovisual synchronization.
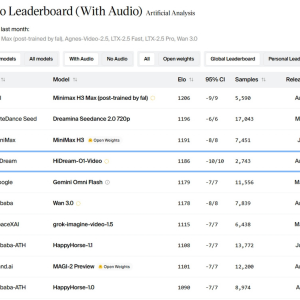
In its debut on two independent international benchmarks, HiDream V1 ranked No. 4 globally on the Artificial Analysis Image to Video Leaderboard (With Audio) and No. 8 on the Arena.ai Image-to-Video leaderboard, placing it among the world’s leading video generation models.
Artificial Analysis independently evaluates leading AI models through standardized and reproducible benchmark testing. Arena.ai uses anonymous head-to-head comparisons and user voting to assess model outputs. Together, the two platforms provide third-party perspectives on model performance based on both standardized testing and real-world user preferences.
HiDream V1’s results demonstrate its competitiveness across key dimensions including visual quality, prompt adherence, motion quality, narrative coherence and audiovisual coordination.
The global AI video generation market has become increasingly competitive, with models developed by Chinese teams—including Seedance and MiniMax H3—maintaining strong positions on international leaderboards. HiDream V1’s top-tier debut further expands China’s presence among the world’s leading video generation models.
“The next generation of video models will not be defined solely by higher resolution or longer duration,” said Yao Ting, Chief Technology Officer of HiDream.ai. “What matters is whether a model can genuinely understand a creator’s intent and how objects, actions and sounds interact in the real world. HiDream V1 was designed from the outset to represent text, video and audio within a unified framework. Our goal is to move video generation beyond simply looking sharp and moving smoothly toward understanding instructions, sustaining coherent performances and keeping sound aligned with visuals. Its performance on two independent international benchmarks provides encouraging validation of our native omnimodal approach.”
Upgrades in Visual Fidelity, Narrative Coherence and Character Consistency
HiDream V1 introduces broad improvements in high-fidelity rendering, narrative continuity and character consistency. Rather than optimizing only for the quality of individual frames, the model is designed to maintain coherence across an entire video sequence.
Once characters, emotions, motivations and physical rules are placed within a continuous sequence, each element can affect the others. HiDream therefore uses a technical framework built around three stages: planning first, followed by joint generation, and then alignment through multimodal reward signals.
Under this approach, the model first plans the narrative and character states at a global level. It then jointly constrains visuals, movement and semantics during generation, before using multimodal reward signals to align visual quality, continuity and physical plausibility.
Native Omnimodal Architecture for Better Intent and Physics Understanding
The central challenge in AI video generation is shifting from the quality of individual frames to a broader understanding of complex instructions, continuous motion and the rules governing the physical world.
User prompts often contain multiple layers of information, including characters, actions, settings, camera directions, dialogue and sound. To handle these requirements more effectively, HiDream V1 incorporates multimodal intent understanding and planning. Before generation begins, the model structures the user’s request across elements such as shot duration, setting, character state, movement, facial expression, composition, camera motion, dialogue and ambient sound.
Through this “understand, plan and generate” workflow, HiDream V1 plans narrative development and character states at a global level, while coordinating visuals, motion, semantics and audio during generation. This is designed to improve content completeness, character consistency and continuity between shots.
Physical reasoning is another core capability of HiDream V1. The model incorporates factors such as gravity, inertia, collisions, deformation, materials, lighting and spatial continuity into the generation process. As a result, object movement, character actions and environmental responses can more closely reflect the behavior of the real world.
This approach moves video generation beyond reproducing visual appearances and toward modeling how a dynamic world operates over time.
Content-Adaptive Video Duration
Most current video generation models require users to specify a fixed duration in advance, forcing the content to fit within a predetermined time window. This can lead to unnecessary pauses after an action has ended or the use of slow motion to fill the remaining time.
HiDream V1 instead incorporates duration into its narrative planning process. Within a range of 5 to 20 seconds, the model can determine an appropriate video length based on how an event unfolds, how long an action takes to complete and the pacing required by the content.
The capability is not simply a matter of adding or removing frames. It is designed to make duration serve the narrative, producing more natural pacing and more complete sequences. Users can focus on describing the event and intended outcome, while the model plans the corresponding temporal structure.
Conventional AI video generation systems often follow a staged workflow in which visuals are generated first and sound is added afterward. This can lead to mismatches between lip movements, physical actions, ambient sound and sound effects.
HiDream V1 uses a native omnimodal architecture to jointly model text, video and audio signals. The three modalities constrain and inform one another within a single generation process. Visual motion influences sound timing, dialogue and sound effects contribute to the emotional tone of a scene, and text conditions guide the generation process throughout.
This unified approach is designed to improve synchronization across character performance, environmental changes and physical actions.
During post-training, HiDream uses Diffusion Reinforcement Learning and a multimodal reward model aligned with human perception and aesthetic preferences. Generated content is evaluated across multiple dimensions, including visual quality, semantics, motion, physical plausibility and sound, helping improve overall consistency and realism.
Completing HiDream’s Native Omnimodal World Model Portfolio
HiDream V1 is not a standalone model. It is a core component of HiDream’s native omnimodal world model strategy.
Built on a unified UiT, or Unified Transformer, foundation, the company’s portfolio now comprises four major model families:
- HiDream-O1-Image, for image understanding and generation;
- HiDream-O1-Video, for dynamic content generation and temporal storytelling;
- HiDream-O1-World, for 3D environment simulation and real-time interaction; and
- HiDream-O1-Embodied, for spatial reasoning, action planning and feedback in embodied AI.
Rather than operating as four separate technology stacks, the models are designed to evolve from the same unified architecture. Together, they cover spatial understanding, temporal modeling, 3D interaction and embodied action, creating an integrated system for perceiving, understanding, generating, interacting with and acting upon the physical world.
HiDream’s models have previously achieved leading results on several independent benchmarks. HiDream-O1-Image 1.5, the commercial version of the company’s image model, ranked No. 2 globally and No. 1 among Chinese models on the Artificial Analysis text-to-image leaderboard, while its open-source edition also reached No. 2. HiDream-O1-World ranked No. 1 overall on WBench, a benchmark for interactive world models. HiDream-O1-Embodied achieved first-place results in the disturbance adaptation and spatial reasoning categories of RoboColiseum.
“We are not building four isolated model product lines,” said Dr. Mei Tao, founder and CEO of HiDream.ai. “We are building a native omnimodal system that shares a unified technical foundation and continues to evolve toward a deeper understanding of the real world. Competition among the next generation of foundation models will depend not only on improvements in individual capabilities, but also on whether different modalities can understand, generate and interact within a unified architecture.”
From understanding and generating the world to simulating and acting within it, the launch of HiDream V1 completes a key part of HiDream’s native omnimodal world model portfolio.
Alongside the launch of HiDream V1, HiDream announced the completion of a Series C+ financing round backed by New Micro Capital, Jiaozi Capital and ICBC Capital. The proceeds will support native omnimodal model research and development, product iteration, AI computing infrastructure and the expansion of industry applications.
New Micro Capital was jointly established by Shanghai New Micro Technology Group, Shanghai Science and Technology Venture Capital Group and its management team. The firm manages nearly RMB 10 billion in assets.
As the corporate venture capital arm of New Micro Technology Group, New Micro Capital is expanding its investments in artificial intelligence. Drawing on the group’s industrial capabilities in specialty integrated-circuit manufacturing, it seeks to advance collaboration across AI infrastructure, model technologies and end-user applications.
Jiaozi Capital is a wholly owned state-backed equity investment platform under Chengdu Jiaozi Financial Holding Group. The firm focuses on artificial intelligence and other strategic technology sectors, using long-term capital and industrial resources to accelerate technology commercialization and ecosystem development.
With the launch of HiDream V1, HiDream’s native omnimodal world model strategy is moving from a technical roadmap toward an integrated system supported by a unified foundation, a coordinated model portfolio and deployable product capabilities.
HiDream V1 is currently in internal testing and is expected to become available in the near future. Users can learn more at: https://hiharness.ai/
Hashtag: #HiDreamAI
The issuer is solely responsible for the content of this announcement.
About HiDream.ai
HiDream.ai is an artificial intelligence company focused on generative AI and native omnimodal world models. Built on its unified UiT architecture, the company’s model portfolio spans image generation, video generation, interactive world simulation and embodied intelligence. HiDream aims to develop AI systems capable of understanding, generating, simulating and acting upon the real world.
Leaderboard disclaimer: Rankings cited in this release reflect publicly available results at the time of publication and may change as participating models, evaluation data or platform methodologies are updated.

Views: 6